Welcome to my portfolio

Hi, I'm Aashish TimsinaBackend Developer & Web Scraper in Nepal

Backend D

I'm a web scraper and backend developer specializing in data extraction, automation, and building scalable server-side systems. From SERP scraping and eCommerce price monitoring to crafting robust APIs with Node.js, Express.js, MongoDB, and MySQL — I build solutions that turn raw data into real business value.

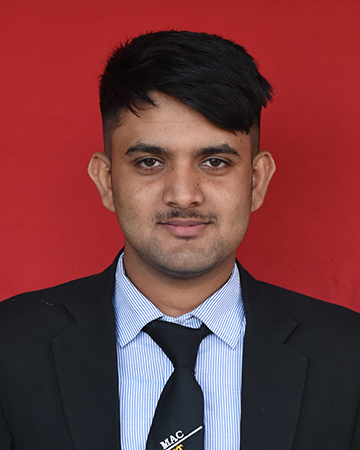
Aashish Timsina, backend developer and web scraper in Pokhara, Nepal
<Node.js/>
<MongoDB/>
<Express.js/>
Scroll Down

About

I turn messy websites into clean, usable data.

I started out curious about how data moves across the web, and that turned into a specialty: automated pipelines that collect, clean and structure data from sites that don't offer an API.

I build scrapers for eCommerce price monitoring, SERP tracking, lead generation and competitor analysis, designed to cope with anti-bot measures, JavaScript-rendered pages and large crawls.

I also build the backend around the scraper (REST APIs, PostgreSQL, MongoDB and MySQL, scheduling) so the data ends up somewhere you can actually use it.

Based in
Pokhara, Nepal
Experience
3+ years
Focus
Web scraping, backend APIs, data pipelines
Works with
Python, Node.js, Scrapy, Playwright, PostgreSQL
Clients
Nepal and worldwide, remote

Scraping & crawling

Scrapy, Playwright, Puppeteer, Cheerio, Selenium

Backend

Python, Node.js, Express.js, REST API design

Data & storage

PostgreSQL, MongoDB, MySQL, automated ETL

Automation

Cron jobs, proxy rotation, anti-bot handling

Services

What I build

Web scraping services in Nepal, from automated data extraction to the backend systems that store, schedule and serve the data.

01 / Collect

Get the data

Scrapers and crawlers that pull structured data from sites with no API, including JavaScript-heavy pages.

Core service

Web Scraping Services

Professional web scraping services in Nepal: automated data extraction from eCommerce platforms, business directories, and any website at scale.

  • Handles JavaScript-rendered pages
  • Output as JSON, CSV or through an API
  • Scheduled, repeatable runs
ScrapyPlaywrightPuppeteer

SERP & Competitor Scraping

Track search engine rankings, monitor competitor pricing, and extract keyword data automatically.

  • Keyword rank tracking over time
  • Competitor price and listing monitoring
  • Proxy rotation to avoid blocks
PlaywrightProxy rotationCron

Scraping Bot & Automation

Headless browser automation for JavaScript-rendered pages, anti-bot measures and scheduled crawlers.

  • Puppeteer and Playwright browsers
  • Anti-bot and proxy handling
  • Crawlers that run on a schedule
PuppeteerPlaywrightHeadless
02 / Store

Clean and store it

Raw pages become clean, structured records in a database you can query.

Data Extraction & ETL

End-to-end pipelines that collect raw web data and deliver it clean and structured for your business.

  • Extract, clean and structure raw data
  • Load into SQL or NoSQL databases
  • Delivery as files or through an API
PythonNode.jsPostgreSQL

Database Design & Storage

Designing and optimizing PostgreSQL, MongoDB and MySQL databases to store, query, and manage large volumes of scraped data.

  • Schema design for large datasets
  • PostgreSQL, MongoDB and MySQL
  • Query and storage optimization
PostgreSQLMongoDBMySQL
03 / Build

Put it to work

The backend that schedules scrapers, stores results and exposes the data to your tools.

Back-End Development

Robust server-side systems built with Node.js, Python and Express, handling authentication, data storage, scheduling, and scraper orchestration.

  • Node.js and Python services
  • Authentication and data storage
  • Scheduling and scraper orchestration
Node.jsPythonExpress

API Development

Custom REST APIs that expose your scraped datasets, trigger collection and integrate with your existing tools and workflows.

  • REST APIs for your scraped data
  • Trigger collection through endpoints
  • Integrates with your existing tools
RESTExpressNode.js

Process

How a project runs

  1. Step 1

    Brief

    You tell me which sites, which fields and how often. I check what is feasible and what blocks to expect.

  2. Step 2

    Build

    I write the scraper and the API or database around it, with logging and retries from day one.

  3. Step 3

    Deliver

    Data arrives as JSON, CSV or through an API, on a schedule that fits your workflow.

  4. Step 4

    Maintain

    Sites change. I monitor failures and fix selectors and anti-bot issues as they appear.

Work

Web Scraping & Backend Projects

Web scraping tools, data extraction pipelines and backend systems built for businesses in Nepal and beyond.

More on GitHub
01Featured

eCommerce Price Scraper

Automated price monitoring scraper built with Puppeteer and Node.js that tracks product prices across multiple eCommerce platforms in Nepal. Sends alerts on price drops and stores historical data in MongoDB for trend analysis.

  • Node.js
  • Puppeteer
  • MongoDB
  • Cron Jobs
  • REST API
02Web Scraping

SERP Rank Tracker

A SERP scraping tool that monitors keyword rankings on Google search results. Built with Playwright for JavaScript-rendered pages, proxy rotation for anti-bot bypass, and a dashboard API to visualize ranking trends over time.

  • Playwright
  • Node.js
  • Proxy Rotation
  • Express
  • MySQL
03Web Scraping

Business Directory Scraper

Bulk data extraction tool for scraping business listings, contact details, and addresses from online directories. Features deduplication, CSV/JSON export, and scheduled auto-runs via cron jobs.

  • Cheerio
  • Node.js
  • MongoDB
  • Axios
  • Cron Jobs
04Web Scraping

Lead Generation Scraper

Automated lead scraping pipeline that extracts business emails, phone numbers, and social profiles from targeted websites. Data is cleaned, deduplicated, and delivered via REST API for CRM integration.

  • Node.js
  • Puppeteer
  • Express
  • MongoDB
  • REST API
05Backend

School Management System

A comprehensive Node.js and Express backend for school management with event system and library resource management. Features RESTful API architecture, JWT authentication, and role-based access control.

  • Node.js
  • Express
  • MongoDB
  • JWT
  • REST API
06Backend

Job Finder Platform

MERN stack application with real-time job listings, advanced filtering, and user authentication. Backend features include worker profiles, job matching algorithms, and notification systems.

  • MongoDB
  • Express
  • React
  • Node.js
  • Socket.io
07Web Scraping

Scrapy Crawler Pipeline

A Python Scrapy project that crawls multi-page sites, cleans the extracted items in item pipelines and stores them in PostgreSQL.

  • Python
  • Scrapy
  • PostgreSQL
08Web Scraping

Node.js Playwright Scraper API

A Node.js scraper that uses Playwright for JavaScript-rendered pages and serves the collected data through a REST API.

  • Node.js
  • Playwright
  • Express
  • REST API
Get in Touch

Contact Me

Have a project in mind or want to discuss a collaboration? I'd love to hear from you.

Hello! I'm Aashish Timsina, a dedicated and creative developer who thrives on transforming ideas into seamless digital experiences. With a strong foundation in backend development and a constant hunger for learning, I am committed to pushing the boundaries of what's possible in the digital landscape.

Our Location

Tallakot, Pokhara-kaski, Nepal 33700

Phone Number

(+977) 9861524169

Email Address

[email protected]

Connect With Me